Usage
Monitor your AI platform usage with detailed insights into resource consumption and performance metrics. Track usage patterns and optimize your AI workloads through comprehensive analytics and historical data.
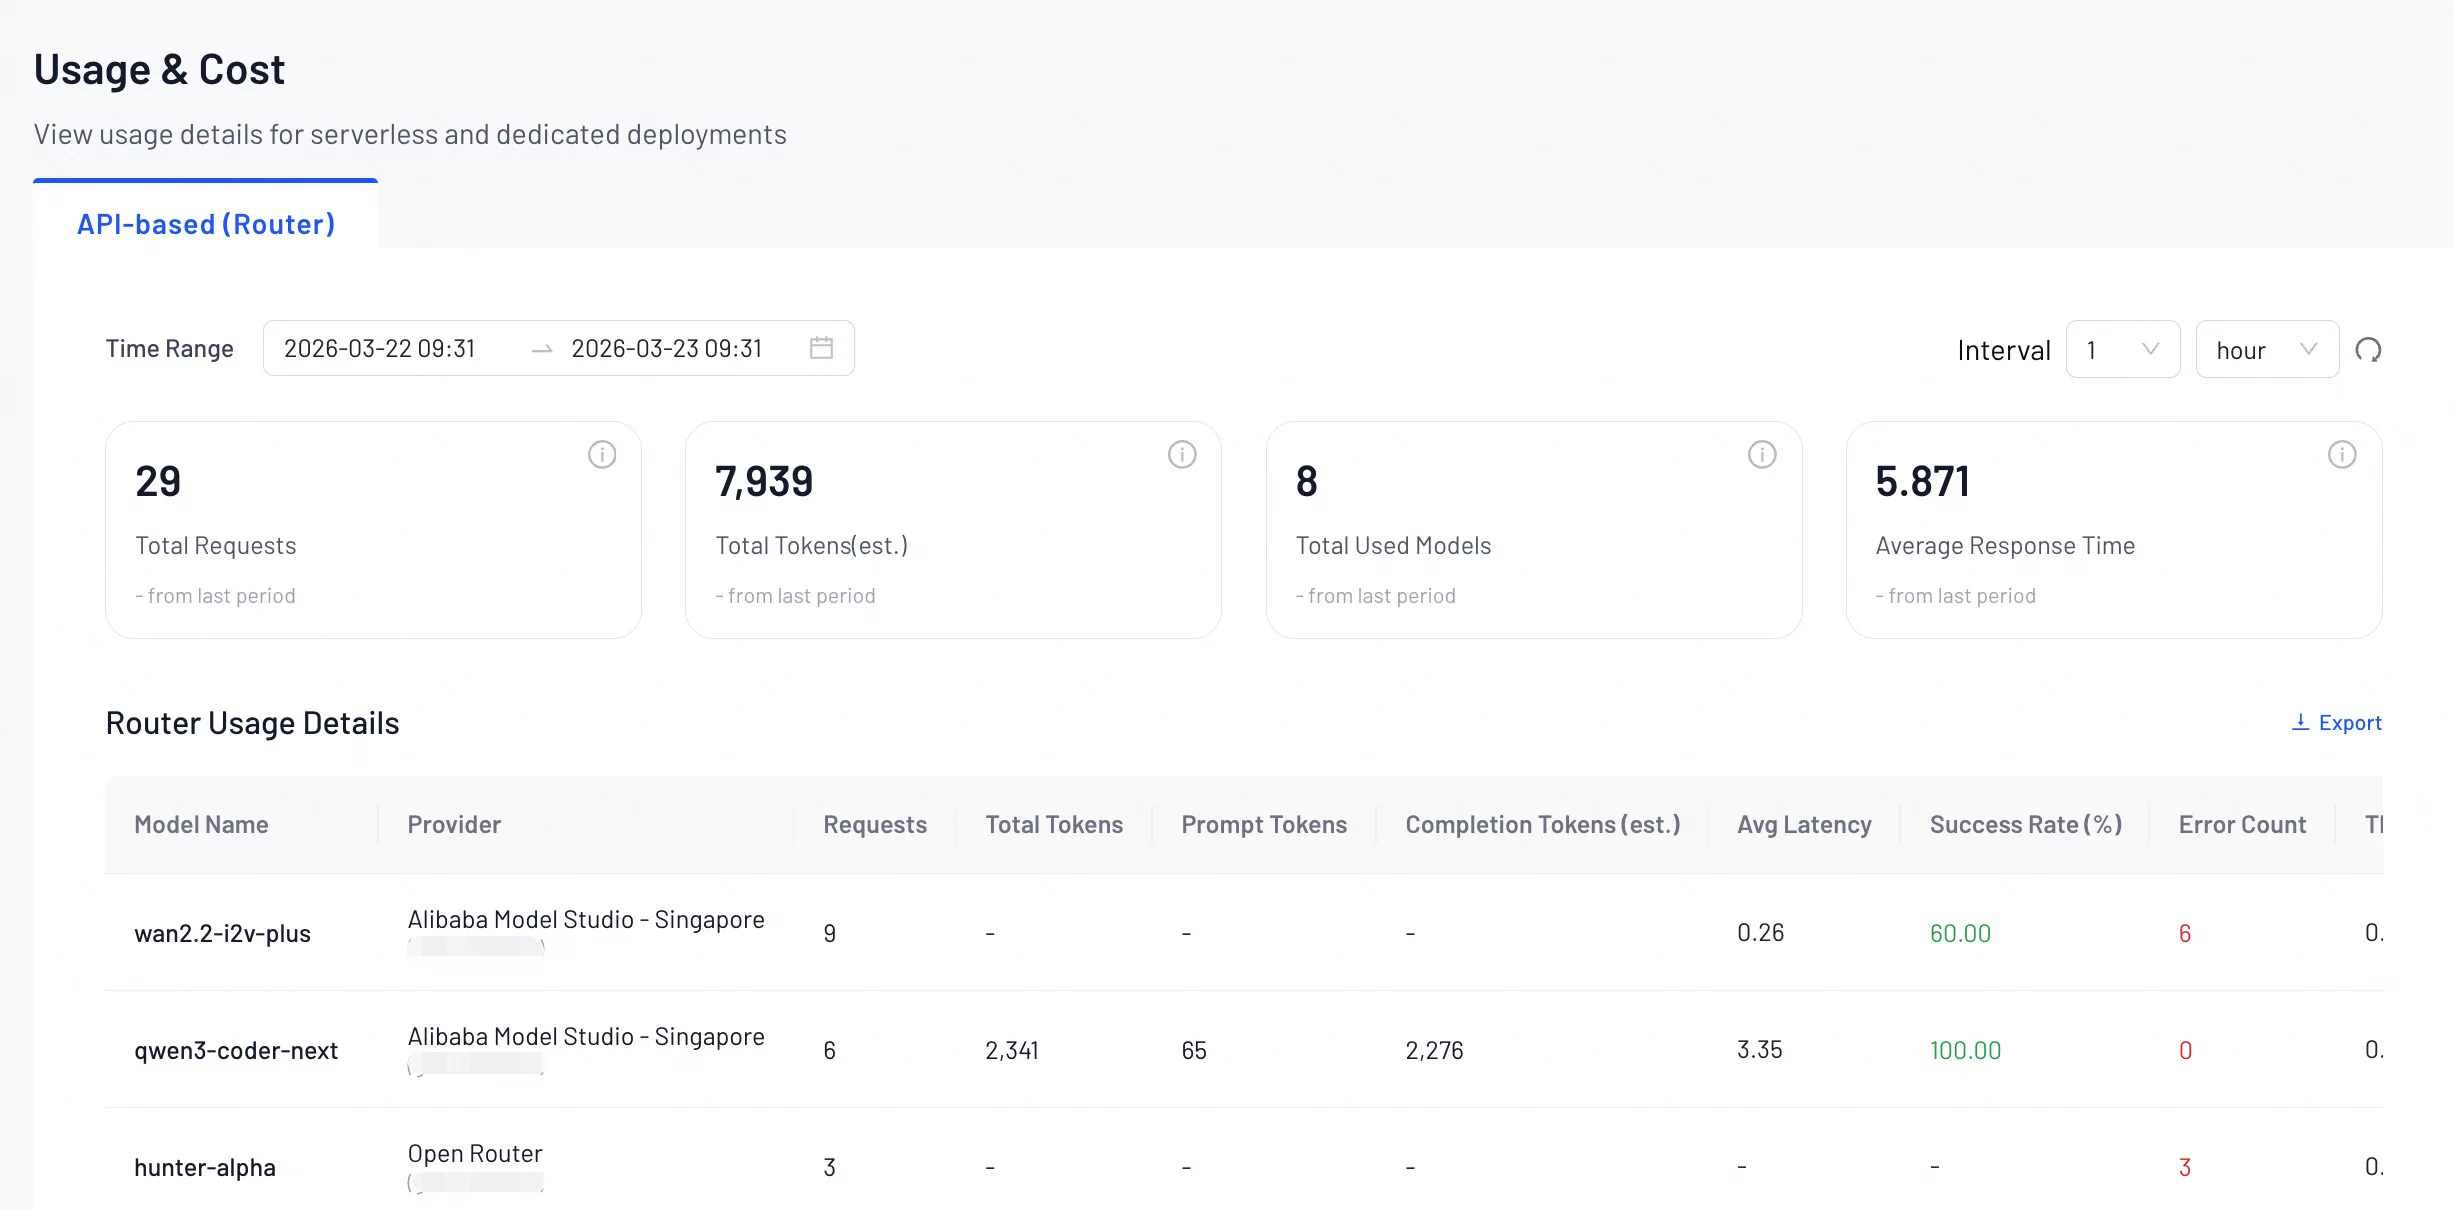
Router Metrics Overview
- Total Requests: The total number of API requests processed by the router.
- Total Tokens (est.): The estimated total number of tokens consumed by all router requests.
- Total Used Models: The number of unique AI models accessed through the router during the selected time period.
- AVG Response Time: The average response time for router requests measured in seconds.
Serverless Usage Details
| Name | Description |
|---|---|
| Model Name | The specific AI model identifier used for serverless inference. |
| Provider | The service provider hosting the model. |
| Requests | The number of API calls made to this specific model through the router. |
| Total Tokens (est.) | The estimated token consumption for this model, including both input and output tokens. |
| Prompt Tokens (est.) | The estimated number of input tokens sent to the model. |
| Completion Tokens (est.) | The estimated number of output tokens generated by the model. |
| Avg. Latency | The average response time for this specific model, measured in seconds. |
| Success Rate (%) | The percentage of successful requests for this model. |
| Error Count | The total number of failed requests for this model during the selected time period. |
| Throughput (QPS) | The number of queries processed per second by this model. |