Models
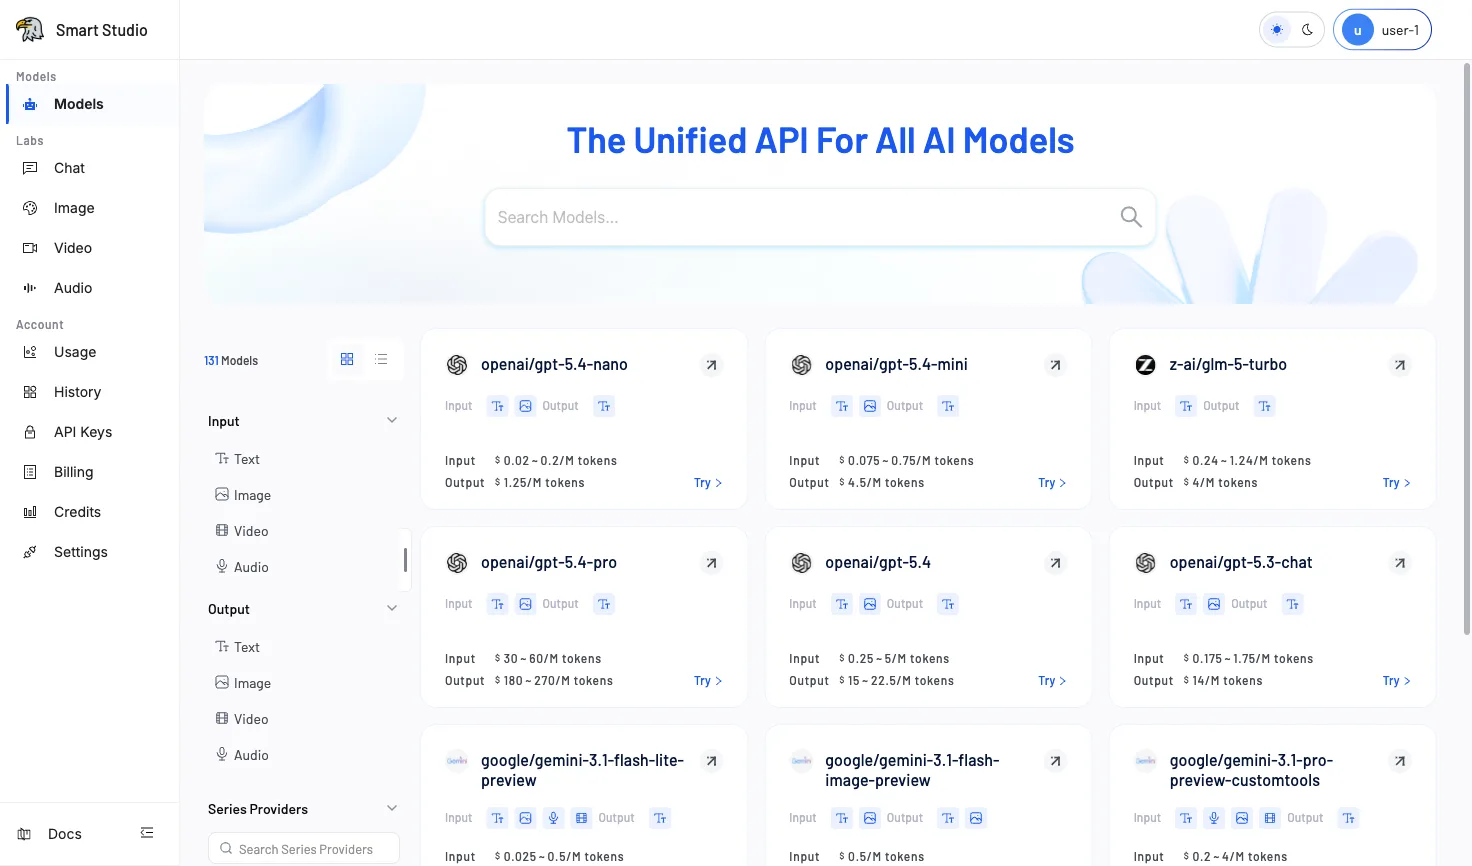
Selecting the right model for your use case is crucial for optimal performance. This guide helps you find the best models for your project.
Understand Model Types
Learn about different model types to choose the right model for your needs.
Model Types
| Model Type | Description | Representative Models |
|---|---|---|
| Large Language Models (LLM) | Handle natural language tasks such as text generation, comprehension, summarization, and reasoning. | Qwen, GLM, DeepSeek, etc. |
| Vision-Language Models (VLM) | Integrate image and text modalities to support image captioning, visual question answering, and multimodal understanding. | Qwen3-VL, Qwen2.5-Omni, MedGemma, etc. |
| Image Models | Focus on image generation, editing, and recognition through computer vision techniques. | Qwen-Image, Wan, Flux, etc. |
| Video Models | Extend image modeling into temporal sequences, enabling video understanding and captioning. | Wan, CogVideo, HunyuanVideo, etc. |
LLM
Large Language Models excel at natural language understanding, reasoning, and generation across diverse tasks and domains.
| Use Case | Description | Recommended Models |
|---|---|---|
| Code & Development | Generate code, debug, explain logic, assist programming | claude-sonnet-4.6, claude-opus-4.6, etc. |
| Agent | Build autonomous agents for multi-step tasks, tool use | claude-opus-4.6, deepseek-v3.2, etc. |
| Reasoning | Perform multi-step logic, math reasoning, structured thinking | claude-opus-4.6, glm-5-turbo, etc. |
| Conversation | Enable multi-turn dialogue for chatbots and assistants | gemini-3-flash-preview, mimo-v2-pro, claude-sonnet-4.5, etc. |
VLM
VLMs process images and text together for multimodal understanding tasks.
| Use Case | Description | Recommended Models |
|---|---|---|
| Visual Question Answering (VQA) | Answer complex questions based on images or videos, combining visual perception and language understanding. | Qwen3.5-Flash, Qwen3-VL-Plus, etc. |
| Image Captioning | Automatically generate descriptive captions for images to improve accessibility and content indexing. | Qwen3.5-Flash, Qwen3-VL-Plus, etc. |
| Real-time Video Conversation | Engage in spoken conversations about live video streams, enabling interactive, real-time analysis. | Qwen3.5-Flash, Qwen3-VL-Plus, etc. |
Image Model
Generate and edit images for business and creative applications.
| Use Case | Description | Recommended Models |
|---|---|---|
| Text to Image (T2I) | Generate detailed images directly from text prompts, ideal for creative design and content creation. | wan2.6-t2i, qwen-image-plus, etc. |
| Image to Image (I2I) | Modify existing images guided by textual input for style transfer or enhancement. | wan2.6-image, wan2.5-i2i-preview, etc. |
| E-commerce Product Images | Generate marketing and product display images for e-commerce platforms. | wan2.6-image, wan2.5-i2i-preview, etc. |
| Social Media Content Creation | Create visual content for social media platforms and marketing campaigns. | qwen-image-plus, wan2.6-t2i, etc. |
Video Model
Create videos from text descriptions or static images.
| Use Case | Description | Recommended Models |
|---|---|---|
| Text to Video (T2V) | Create videos based on textual descriptions. | wan2.6-t2v, wan2.5-t2v-preview, etc. |
| Image to Video (I2V) | Generate videos from static images with smooth movement synthesis. | wan2.6-i2v, wan2.2-i2v-plus, etc. |
| E-commerce Product Ads | Create product advertisement videos from text or images. | wan2.2-i2v-plus, wan2.1-i2v-turbo, etc. |
| Social Media Snippets | Create short video content for social media platforms and marketing. | wan2.6-i2v-flash, wan2.2-kf2v-flash, etc. |
| Character Consistency | Generate animated avatars and digital humans for videos with consistent character representation. | wan2.6-r2v, wan2.6-r2v-flash, etc. |
Open Models (in your deployed Console). The Console catalog is the source of truth for models available to your tenant.
Next Steps
Browse our comprehensive model catalog and find the perfect model for your use case.
Experience and compare different model outputs in our interactive playground.